.svg)
Running LLMs Locally: From Terabytes to Tokens
Video
Presenters
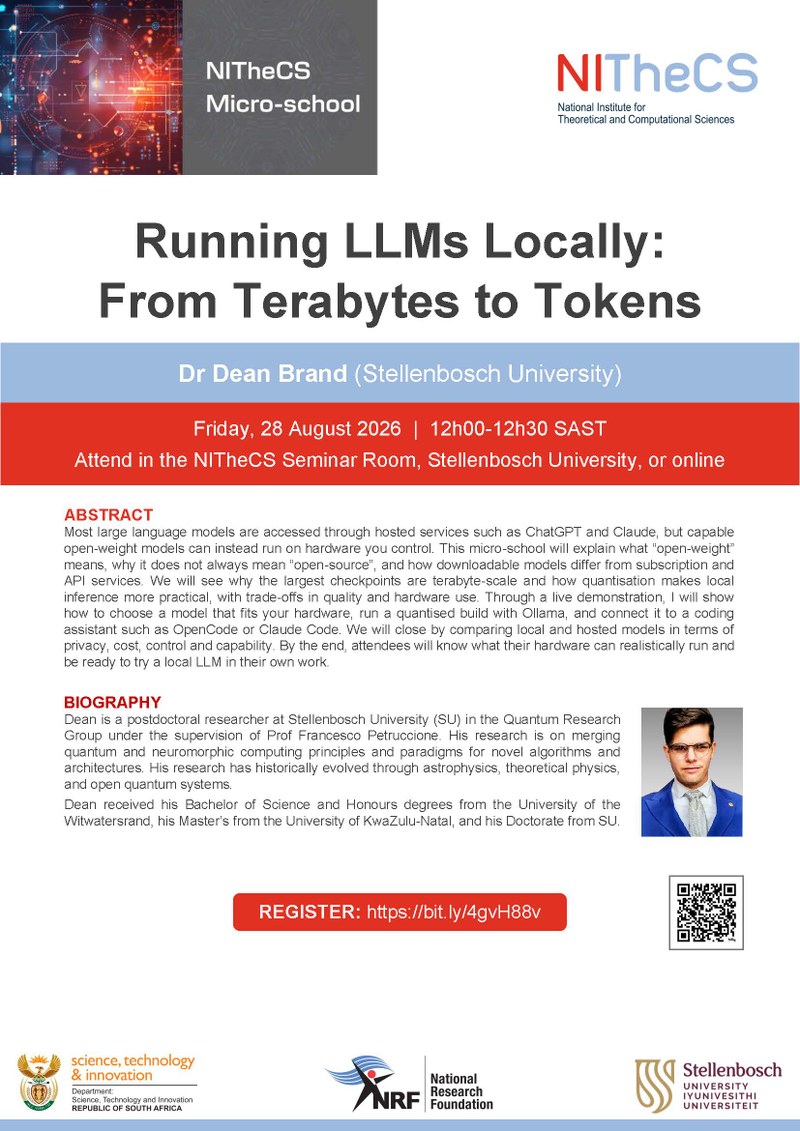
Poster
Details
This micro-school will explain what “open-weight” means, why it does not always mean “open-source”, and how downloadable models differ from subscription and API services. We will see why the largest checkpoints are terabyte-scale and how quantisation makes local inference more practical, with trade-offs in quality and hardware use. Through a live demonstration, I will show how to choose a model that fits your hardware, run a quantised build with Ollama, and connect it to a coding assistant such as OpenCode or Claude Code. We will close by comparing local and hosted models in terms of privacy, cost, control and capability. By the end, attendees will know what their hardware can realistically run and be ready to try a local LLM in their own work.
Alternative Viewing Locations
- Online
Materials